Guides / Stable column mapping
Keep CSV Columns Aligned When JSON Object Keys Change Order
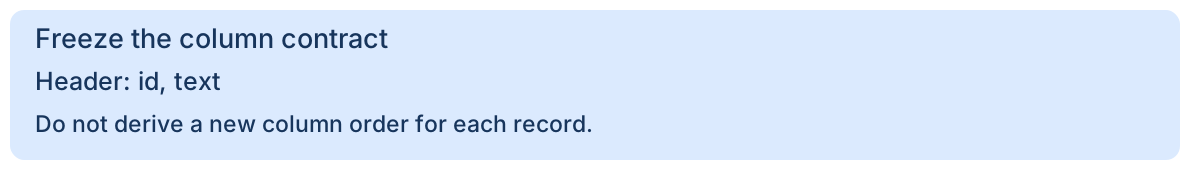
Choose one CSV header order, then retrieve each row's values by those field names. For id,text, always write [row["id"], row["text"]]. Writing each object's values() can silently swap fields when the source objects use different key orders.
The same fields can arrive in a different order
A batch can contain records from two producers that serialize the same keys differently. That does not give the second record a new CSV schema. CSV columns have positions, so the exporter needs a single field-to-position mapping for the whole file.
[
  {"id": "A01", "text": "North"},
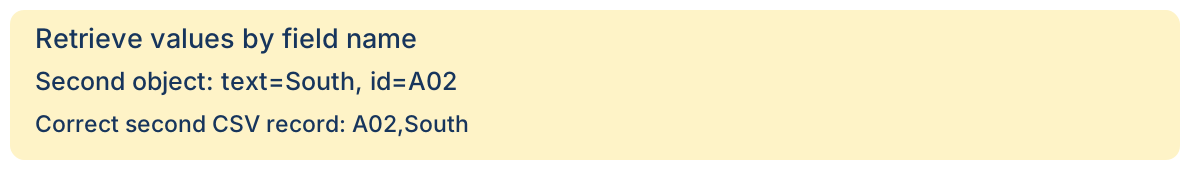
  {"text": "South", "id": "A02"}
]
RFC 8259 defines a JSON object as an unordered collection. A parser may expose an iteration order, but using that as a different column mapping for every record creates an avoidable dependency on how the producer wrote the object.
Our counterexample passes a row-count check
We ran both mappings on 2026-10-20 with Python 3.12.14. Here are their parsed field matrices, including the shared header. This is a fictional fixture and an executed local example, not a report of a customer's data.
Wrong: header + each record's values()
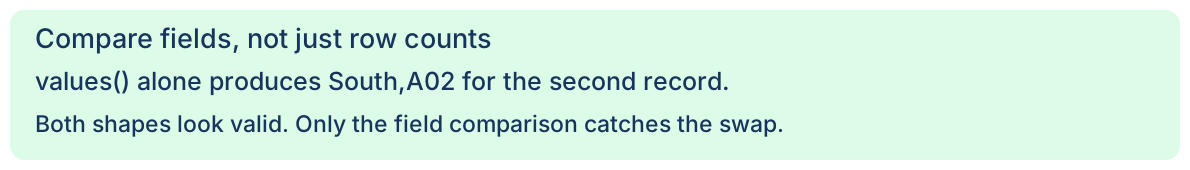
[["id", "text"], ["A01", "North"], ["South", "A02"]]

Correct: header + values retrieved by id, then text
[["id", "text"], ["A01", "North"], ["A02", "South"]]
Both outputs have two data records and two fields per record. Shape and row counts alone cannot detect the second record's misplaced values. The wrong file remains readable CSV, which makes this a field-mapping failure rather than a CSV syntax error.
Declare the order once
fields = ["id", "text"]
writer.writerow(fields)
for row in rows:
    writer.writerow([row[name] for name in fields])
The downloadable recipe validates the full input before opening the output. It requires exactly these keys, so a missing field cannot become an accidental blank and an extra field cannot disappear silently. You can alternatively use csv.DictWriter, whose fieldnames sequence controls the written order. Define your own missing-field and extra-field policies rather than relying on defaults you have not reviewed.
Reproduce the local example
These are independent Python examples, not measurements of the browser converter. Download the input, exporter, saved CSV and execution evidence into one folder. Use Python 3.12 or later and a new output filename.
python explicit-id-text-export.py key-order-input.json new-result.csvThe demonstration contract has exactly two string fields, id and text. It rejects missing or extra keys, non-string values, duplicate object keys, invalid UTF-8 and nonstandard JSON constants. It reads at most 1,000,001 bytes and rejects inputs over the 1,000,000-byte demonstration policy. That limit is a code policy, not a measured browser limit. Arrays, nested objects and automatic type conversion are outside this example.
The output uses UTF-8 and CRLF record endings. Exclusive file creation prevents overwriting an existing file. A disk error may leave a partial file; inspect the error before trying a new filename. Faithful text conversion does not neutralize spreadsheet formulas, so use a suitable text import workflow for untrusted data.
Real question: how do I keep JSON-to-CSV headers usable?
A 2022 Stack Overflow question about converting an array of objects with headers discusses differing fields, and its discussion highlights dependence on object order. Our example isolates the key-order case: identical key sets, deliberately different serialization order, one explicit output schema.
If your objects genuinely have different key sets, that is a separate schema decision. This fixed-schema recipe rejects them. A union-of-keys exporter must determine the complete header before finalizing it and define how absent values are represented. Reordering each object's own keys independently does not solve missing-field semantics.
Compare values under their intended column names
Freeze the header sequence, project each source record in that sequence, read the saved CSV back, and compare the recovered field matrix with that projection. Our exporter performs this exact comparison. It catches the South/A02 swap that counting records cannot catch.
Do not fix a misaligned file by changing its header midway through the file. Correct the mapping and regenerate it from the source. See Verify Every Row and Field for broader checks and header-only output for an empty array for the zero-record case. This page addresses column alignment, not sorting the data records or preserving the order of an object-map export.
The workflow in three original diagrams