Guides / Supplied headers
Convert a JSON Array of Arrays to CSV with a Supplied Header
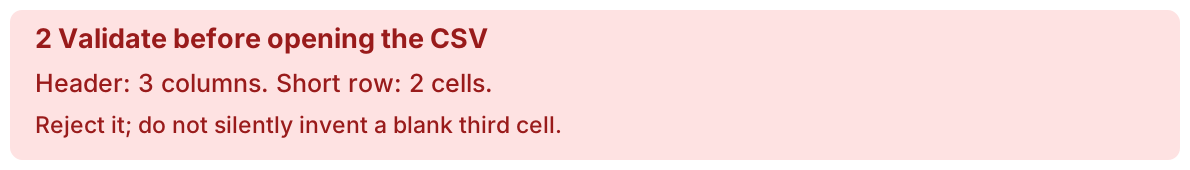
Declare the column names separately, require every row to have exactly that many cells, then write the header followed by the rows with a CSV writer. An array does not supply field names. Reject duplicate headers and short or long rows before creating output; do not silently pad, truncate, or guess that the first row is a header.
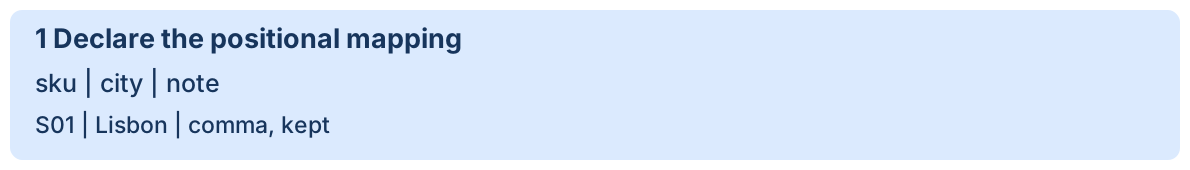
Position gives the mapping; it does not give the names
In a JSON matrix, the first cell of each row goes under the first declared column, the second under the second, and so on. RFC 8259 defines an array as an ordered sequence; it does not require nested arrays to form a rectangular table. Equal widths are this export contract, rather than a JSON syntax rule.
Our original wrapper supplies the names explicitly. It is a recipe format, not a promise that every browser converter accepts this wrapper. For an API response with just the rows array, obtain the column order from that API's schema before building this input.
{
  "columns": [
    "sku",
    "city",
    "note"
  ],
  "rows": [
    [
      "S01",
      "Lisbon",
      "comma, kept"
    ],
    [
      "S02",
      "Oslo",
      ""
    ]
  ]
}
The empty final string in the second row is present data. It is different from a two-cell row that never supplied that third cell. Both may look blank in a spreadsheet, so make the distinction before export.
Check every width before creating the file
For the declared header ["sku","city","note"], this valid row has three cells: ["S02","Oslo",""]. The short row ["S01","Lisbon"] is rejected; the long row ["S01","Lisbon","note","extra"] is also rejected. Neither gets repaired automatically. A missing field may mean an incomplete export, while an extra field may signal a changed upstream schema.
A plain positional mapping such as dict(zip(columns, row)) can omit unmatched values because ordinary zip stops at the shorter input, as documented in Python's zip reference. Duplicate column names can also replace an earlier value when used as dictionary keys. Validate lengths and unique names before either operation. This recipe keeps the rows as lists, avoiding unnecessary conversion to dictionaries.
Write CSV with a parser-compatible contract
python matrix-to-csv.py matrix-input.json new-matrix-output.csvThe downloadable exporter uses Python 3 and requires an object containing only columns and rows. Column names must be nonempty, distinct strings; every cell must be a string. It rejects numbers, booleans, null and nested cells instead of silently choosing a conversion policy. Empty rows collection is allowed and produces just the supplied header.
All validation happens before the output file is opened. The output uses exclusive creation, so an existing file is not overwritten. The recipe loads the complete JSON in memory and applies a 2,000,000-byte policy cap; it is not a streaming converter.
sku,city,note
S01,Lisbon,"comma, kept"
S02,Oslo,
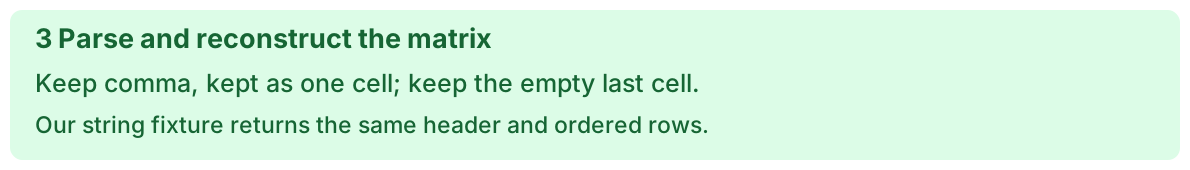
Python's CSV writer handles commas and quotes through CSV escaping; open the file with newline='' as its documentation specifies. In our measured output, comma, kept is one quoted field. The second row's trailing empty string remains a third field. Do not reconstruct either row by splitting on commas.
Read back the header and ordered cells
import csv, json
with open("matrix-input.json", encoding="utf-8") as f:
    original = json.load(f)
with open("new-matrix-output.csv", encoding="utf-8", newline="") as f:
    parsed = list(csv.reader(f))
if not parsed or parsed[0] != original["columns"]:
    raise ValueError("header differs from declared columns")
if any(len(row) != len(parsed[0]) for row in parsed[1:]):
    raise ValueError("CSV contains a ragged row")
rebuilt = {"columns": parsed[0], "rows": parsed[1:]}
if rebuilt != original:
    raise ValueError("ordered cells differ after CSV read-back")
For the recipe's string-only schema, this comparison checks column order, row order and every cell value. It does not reproduce JSON whitespace or escape spelling. Keep the original file. The default CSV reader returns string fields; that is why the exporter declares strings rather than claiming a type-preserving round trip for arbitrary JSON values.
What this example established
On 2026-10-09, Python 3.12.14 exported the original two-row, three-column matrix. CSV read-back reconstructed the same column list and ordered rows, including the comma inside the note and the explicit empty final cell. The short-row, long-row, duplicate-header and null-cell counterexamples each exited with an error before creating a CSV. Download the execution evidence to see the exact inputs, parsed output and rejection messages.
These results concern the supplied files and exporter, not a measurement of other conversion tools. CSV quoting does not declare spreadsheet types or make untrusted formulas safe: inspect the source and import identifier columns as text. For mixed-type JSON, agree on an explicit encoding before using a different exporter.
The same contract in three images
For named records, see preserve object-map keys as row IDs. For final checks, verify every row and field.