Guides / Gzip input
Convert .json.gz to CSV Without Trusting the Compressed Size
Decompress with an explicit expanded-byte limit, then decode and validate the JSON before opening the CSV output. Reject data that exceeds the limit or fails gzip integrity checks. A small compressed file is not evidence of a small JSON document. Keep the compressed source for reproducibility.
Two sizes, two separate decisions
A .json.gz file contains compressed data; renaming it to .json does not decompress it. Python's gzip module provides binary reads of decompressed content. Our recipe caps both the compressed input it reads and the expanded JSON bytes it accepts. It performs decompression locally in Python; this page does not claim the site's browser converter accepts gzip uploads.
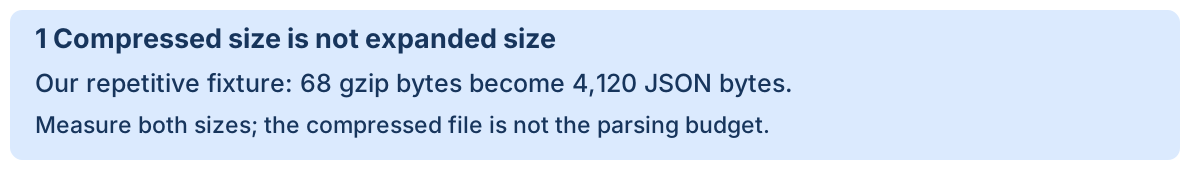
The expandable part is the reason for a second cap. In our generated repetitive fixture, 68 compressed bytes represent 4120 expanded bytes. Those are measurements of that exact fixture, not a general compression ratio or a file-size limit for another tool.
A bounded read before JSON parsing
import gzip, io
with gzip.GzipFile(fileobj=io.BytesIO(compressed), mode='rb') as stream:
    raw = stream.read(limit_bytes + 1)
if len(raw) > limit_bytes:
    raise ValueError('expanded JSON exceeds policy')
# Only now decode and parse raw, then validate the record schema.
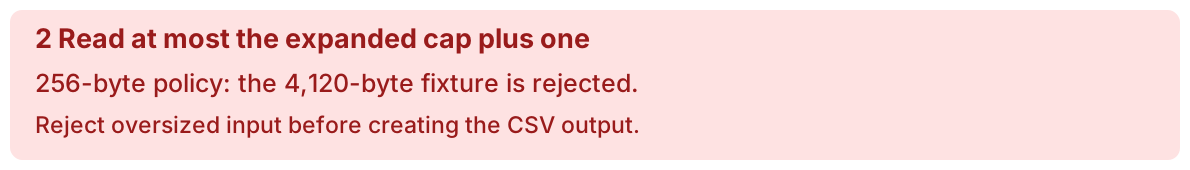
Request one extra byte so an input exactly at the cap can be distinguished from one that exceeds it. This limits the returned expanded byte string; it does not promise that the decompressor's internal buffers, parsed JSON objects or output use that same amount of RAM, or that processing time is bounded.
The downloadable whole-memory recipe reads at most 2,000,001 compressed bytes to enforce its 2,000,000-byte compressed-input policy. Its adjustable expanded cap is between 1 and 2,000,000 bytes. These are deliberate recipe policies, not observed universal thresholds. The JSON documentation also cautions that untrusted input can consume CPU and memory. Run unknown files in an appropriately restricted environment; a byte cap alone is not a complete resource sandbox.
Run the original fixture
python gzip-to-csv.py gzip-input.json.gz new-output.csv --limit-bytes 256
python gzip-verify.py
Download the files below into one folder and use Python 3.12 or later. Our original expanded input is:
[{"id":"G1","note":"small reproducible input for a bounded gzip decompression example"}]
On 2026-10-12, Python 3.12.14 read 102 bytes of gzip input and recovered 89 bytes of UTF-8 JSON. The exported CSV reconstructed the original ordered records and strings exactly. The cap of 256 bytes belongs to this demonstration.
Reject before opening the CSV
| Executed case | Expanded cap (bytes) | Observed result |
|---|---|---|
| accepted | 256 | CSV created |
| exact-cap | 89 | CSV created |
| one-byte-below | 88 | Rejected; no output created |
| expanded-over-cap | 256 | Rejected; no output created |
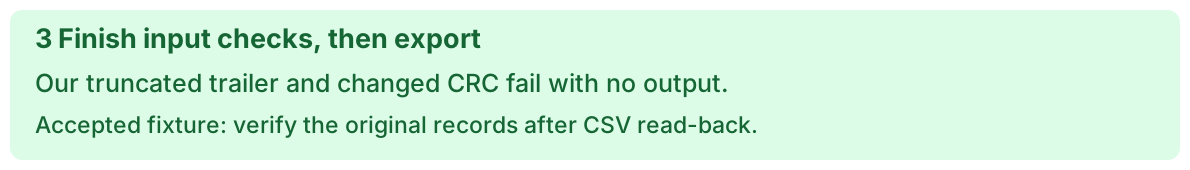
| truncated-trailer | 256 | Rejected; no output created |
| bad-crc | 256 | Rejected; no output created |
| invalid-json | 256 | Rejected; no output created |
The first fixture succeeds at exactly 89 bytes and fails at 88 bytes. The repetitive fixture, a missing part of the gzip trailer, a deliberately changed checksum and invalid JSON all fail without creating output. The downloadable evidence contains exit codes and error text. These are our specific executed counterexamples; they are not proof that every malformed input has been tested.
The gzip error reference lists invalid-file exceptions, including BadGzipFile, EOFError and zlib.error. An accepted bounded read must reach the end of the stream; our complete small file and trailer-corruption checks exercise that path. An oversize input is rejected immediately without promising a later checksum check. A checksum is not proof of trusted origin.
After decompression, this recipe requires UTF-8 JSON and an array of objects containing exactly string fields id and note. Duplicate keys, nonstandard numeric constants and strings that cannot be encoded as UTF-8 are rejected. It then uses the CSV writer and exclusive output creation, retaining the input and refusing to overwrite an existing file. A disk/write failure after output creation may still leave a partial CSV; input rejection before output is a different guarantee. CSV quoting does not neutralize spreadsheet formulas in untrusted text.
When this recipe is the wrong fit
A byte cap is a decision to stop, not a way to convert arbitrarily large data in constant memory. If your expanded JSON legitimately exceeds your allowed budget, obtain smaller record batches or design a streaming process with its own limits and completion checks. See stream large JSON with a complete column set. Do not increase the cap simply because the compressed upload looked small.
This recipe expects one complete JSON document after decompression, rather than JSONL or unrelated concatenated documents. Gzip members can contain separate pieces of one document, but each member is not automatically one CSV record. Keep decompression, document parsing and record mapping as separate steps.
The same input contract in three images
After export, use row and field verification for the receiving workflow. For an ordinary uncompressed file, open the JSON to CSV converter.