Guides / Repeated records
Keep Repeated JSON Records as Separate CSV Rows
Export every occurrence in the JSON array, even when its values match another record. Keep a source position and compare the CSV's ordered records against the original array. If order is intentionally irrelevant, compare occurrence counts rather than sets. A set check can pass after repeated rows have disappeared.
Equal values do not establish a duplicate mistake
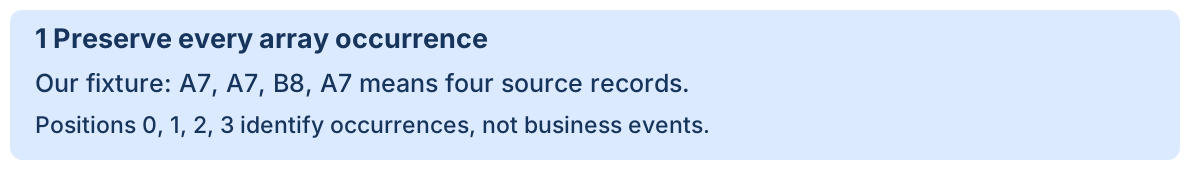
Our original fixture contains four records. The item/status pair A7,ready appears at array positions 0, 1 and 3, while B8,ready appears at position 2. Those are four occurrences, not automatically two business events. The fixture is deliberately fictional; it does not establish what a real system's repeated records mean.
[
  {
    "item": "A7",
    "status": "ready"
  },
  {
    "item": "A7",
    "status": "ready"
  },
  {
    "item": "B8",
    "status": "ready"
  },
  {
    "item": "A7",
    "status": "ready"
  }
]
Choose a deduplication rule only when the source's business contract calls for one. Repetition can be intentional or accidental, and the converter cannot decide that from equality of these fields alone. In this workflow, preserving the supplied array is the contract. Repeated records are different from duplicate names inside one JSON object, which require a separate parsing policy.
Give each occurrence a position, not a made-up business ID
source_position,item,status
0,A7,ready
1,A7,ready
2,B8,ready
3,A7,ready
source_position is our added zero-based array ordinal. It is not an order ID, a globally unique identifier or evidence of chronology. The explicit schema permits only string fields item and status, so there is no existing source_position field to overwrite. A general exporter must reserve a distinct name or reject a collision.
for position, record in enumerate(source):
    writer.writerow([str(position), record['item'], record['status']])
The exporter appends one CSV row for each source record. It does not build a dictionary keyed by item, call a uniqueness function or turn the records into a set. Python's CSV documentation describes row-based reading and writing. The default reader returns fields as strings, which is the contract used by our checker.
python repeated-to-csv.py repeated-input.json new-output.csv
python repeated-verify.py repeated-input.json new-output.csv
Download all files into one folder and use Python 3.12 or later. Running the checker without filenames checks the supplied measured CSV instead. The original JSON remains unchanged. Exclusive output creation refuses to overwrite a file; fix a failed input or choose a new output path instead of replacing existing evidence.
The counterexample: a set hides dropped rows
from collections import Counter
before = [('A7', 'ready'), ('A7', 'ready'),
          ('B8', 'ready'), ('A7', 'ready')]
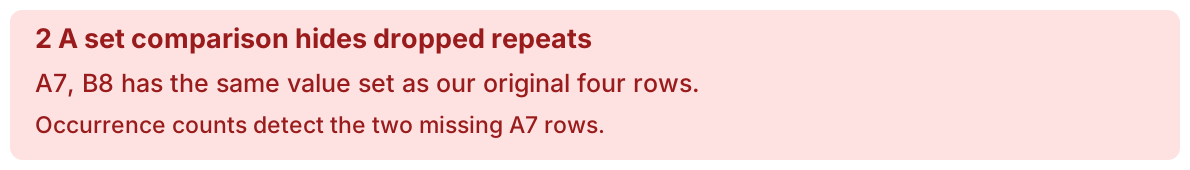
after = [('A7', 'ready'), ('B8', 'ready')]
assert set(before) == set(after)       # Passes despite losing occurrences
assert Counter(before) != Counter(after)
On 2026-10-15, Python 3.12.14 executed our exporter and recovered all four ordered occurrences from CSV. It also executed a two-row deduplicated counterexample: a set comparison passed while the occurrence-count and ordered checks failed. These counts are measurements of this generated fixture, not a prevalence estimate or a test result for another converter.
Python's Counter reference describes counting hashable elements. Here we build tuples in the declared field order so values can be counted. That approach is specific to the string-only schema; nested data or type-preserving comparisons need a deliberate representation.
Counts and order catch different failures
| Executed fixture | Data rows | Same value set | Same multiplicities | Same ordered occurrences |
|---|---|---|---|---|
| accepted | 4 | Pass | Pass | Pass |
| deduplicated | 2 | Pass | Fail | Fail |
| one-occurrence-lost | 3 | Pass | Fail | Fail |
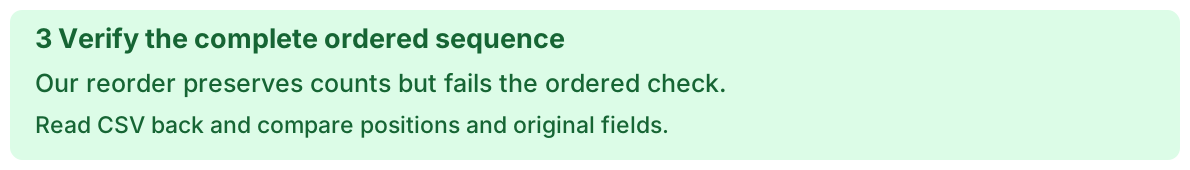
| reordered | 4 | Pass | Pass | Fail |
| same-count-changed | 4 | Pass | Fail | Fail |
The reordered fixture retains the same value multiplicities but fails the ordered occurrence check. The same-count-changed fixture still has four rows and the same distinct value set, yet changes the count of A7 and B8; its Counter comparison fails. A row count alone cannot prove completion.
The downloadable checker validates the exact header, row width and complete ordered sequence, including source_position. It compares positions rather than silently sorting the output back into order. If your downstream system deliberately sorts rows, decide whether physical order belongs to its contract and design that audit explicitly. Counter equality alone cannot detect a permutation.
A position column records where an exported occurrence came from; it does not prevent a receiving program from deduplicating or reordering it. Check the receiving result, not merely the file before import. If the source array itself changed between exports, preserve both source snapshots and do not treat positions as stable business keys.
Keep the demonstration's limits explicit
The exporter requires exactly the item/status string schema, rejects duplicate object keys and nonstandard constants, and validates strings for UTF-8 output before opening CSV. It accepts at most 1,000,000 input bytes under an adjustable-in-code demonstration policy. That cap is not a measured browser limit or a guarantee of total resource use. A write failure after creating the output can still leave a partial file.
These fixtures do not audit a live API or the browser converter, and preserving field text is not spreadsheet formula sanitization. Use the general row and field checklist for the wider workflow. For duplicate names inside an object, see duplicate JSON keys; for an object keyed by record IDs, see object-map export. None of those identities replaces an occurrence in this array.
The same input contract in three images
Open the JSON to CSV converter for an inspectable document, or use this separate local recipe to reproduce the occurrence-preservation checks.