Guides / String line breaks
Preserve JSON String Line Breaks When Converting to CSV
Parse JSON once, pass its string values unchanged to a CSV writer, and read the CSV back with a CSV parser that preserves embedded newlines. JSON \n represents an actual line feed; \\n represents a literal backslash followed by n. Do not replace one with the other. For the Python recipe below, use newline='' on both file opens to keep LF and CRLF distinct.
Three similar-looking notes, three different strings
This original fixture isolates one question: does a string's line-break content survive CSV export? It does not address missing fields, null encoding, positional headers or arbitrary nested data. Those need separate contracts. Inspect the JSON source spelling and the parsed characters separately:
[
  {
    "id": "L1",
    "note": "first\nsecond"
  },
  {
    "id": "L2",
    "note": "first\\nsecond"
  },
  {
    "id": "L3",
    "note": "first\r\nsecond"
  }
]| ID | JSON source escape | Parsed characters between words |
|---|---|---|
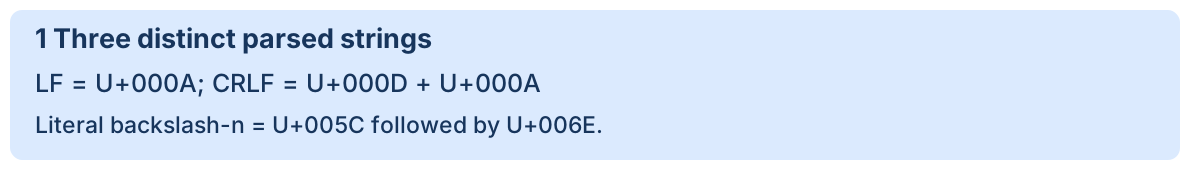
| L1 | \n | LF: U+000A |
| L2 | \\n | Backslash U+005C, then n U+006E |
| L3 | \r\n | CR U+000D followed by LF U+000A |
RFC 8259 section 7 defines JSON string escapes and requires control characters to be escaped inside JSON strings. CSV is a different representation: a quoted CSV field can contain an actual line break. Preserving a parsed string does not mean preserving the original JSON escape spelling, indentation or source bytes.
Keep the line break inside the CSV field
The supplied exporter accepts only an array of objects with exactly two string fields, id and note. It validates the complete input before creating a new file, rejects duplicate JSON keys and nonstandard constants, and refuses to overwrite an existing output. Its 2,000,000-byte cap is our recipe policy, not a measured browser limit. It loads the entire input in memory.
python multiline-to-csv.py multiline-input.json new-output.csv
python multiline-verify.py
Keep the verifier beside the input and run it from that directory. Its output filename is new-output.csv. The exporter explicitly uses CRLF between records. It passes each note unchanged to csv.writer; embedded LF and CRLF are quoted as field content. L2's literal backslash-n needs no newline transformation.
Here is the measured CSV as a Python byte representation; escape notation makes the record separators and embedded characters visible without relying on a spreadsheet's display:
b'id,note\r\nL1,"first\nsecond"\r\nL2,first\\nsecond\r\nL3,"first\r\nsecond"\r\n'A physical line is not necessarily a record
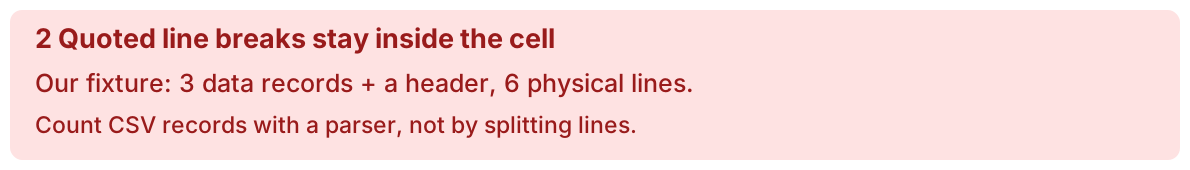
On 2026-10-10, Python 3.12.14 produced 3 data records plus one header from this fixture. Splitting the output bytes with splitlines() produced 6 physical lines, because two notes contain actual line breaks. That is not six CSV records and not proof of extra rows. Parse the quoted fields first, then compare the ordered records and exact strings.
import csv,json
with open("multiline-input.json",encoding="utf-8") as f:
    original=json.load(f)
with open("new-output.csv",encoding="utf-8",newline="") as f:
    records=list(csv.reader(f,strict=True))
if not records or records[0]!=["id","note"]:
    raise ValueError("unexpected header")
rebuilt=[]
for row in records[1:]:
    if len(row)!=2:raise ValueError("unexpected width")
    rebuilt.append(dict(zip(records[0],row,strict=True)))
if rebuilt!=original:raise ValueError("parsed strings changed")
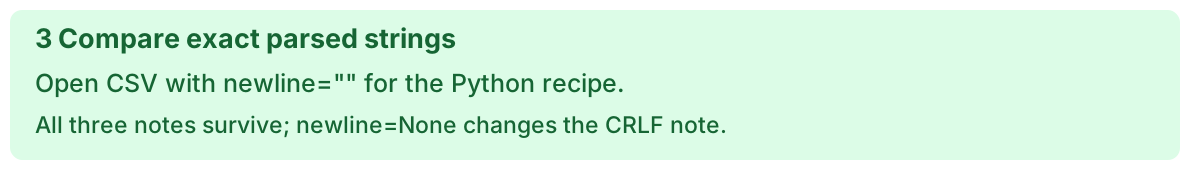
The executed read-back recovered all three notes exactly. L1 kept LF; L2 kept the two characters backslash and n; L3 kept CR followed by LF. Download the evidence for the CSV bytes and each note's code points. This result applies to our fixture and Python recipe; it is not a test of every converter or spreadsheet.
The file-open setting can change a value before comparison
A second executed read-back deliberately opened the same CSV with newline=None. L3 then read as 'first\nsecond' instead of 'first\r\nsecond', so it failed exact comparison. The TextIOWrapper newline contract explains this universal-newline translation. With newline='', line endings are recognized without being translated. The Python CSV documentation also specifies this file-open setting for CSV reading and writing.
Do not repair that difference by replacing every backslash-n in the original JSON. L2 is a counterexample: its literal text would become a different value. Likewise, flattening CRLF to LF may be a valid downstream policy, but it is a transformation that should be documented, not called exact preservation.
If the receiving system requires one physical line per record
First check whether it actually accepts quoted multiline CSV fields. If it cannot, keep the original data and agree on an explicit alternate encoding for the note column, such as JSON-encoded string text. The receiver must decode that column once; it is no longer a plain note value. Avoid ad hoc substitutions, which need their own escape rules to distinguish literal replacement markers from encoded characters.
For a spreadsheet, view the parsed field or formula bar rather than judging by row height. This recipe does not sanitize spreadsheet formulas: review untrusted strings before opening exports. Do not treat correct CSV quoting as protection against formula execution.
The same contract in three images
For broader output checks, see verify every row and field. If the source is a positional matrix, use the separate supplied-header and row-width contract.