Guides / Unicode strings
Keep Unicode Strings Unchanged When Converting JSON to CSV
Export the parsed strings unchanged and verify their code-point sequences after CSV read-back. Apply Unicode normalization only when your receiving system explicitly needs it, and keep the original value separately. Two labels that render alike can contain different character sequences. UTF-8 export alone does not make those sequences identical.
One accent, two representations
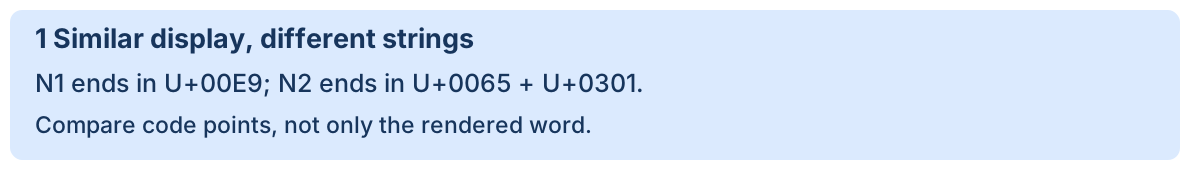
Our original input contains two labels with the same base word and accent, represented differently. The first uses a single precomposed accented letter; the second uses an e followed by a combining acute accent. This page solves the normalization decision, not missing fields, encoding detection or line-break handling.
[
  {
    "id": "N1",
    "label": "caf\u00e9"
  },
  {
    "id": "N2",
    "label": "cafe\u0301"
  }
]| Record | Last part of the parsed string | Last UTF-8 bytes |
|---|---|---|
| N1 | U+00E9 | c3 a9 |
| N2 | U+0065 followed by U+0301 | 65 cc 81 |
The Unicode normalization specification describes canonical equivalence and normalization forms. The distinction matters even when a font displays the same word: screenshot appearance is not an exact string comparison. Our Python equality comparison treats these original labels as distinct.
Preserve first, with an explicit string schema
python unicode-to-csv.py unicode-input.json new-output.csv
python unicode-verify.py
Download the scripts and input to one directory, then run these commands there with Python 3.12 or later. The exporter accepts only objects containing exactly two string fields, id and label. It does not call a normalization function, trim whitespace, change case or transliterate characters. It validates the whole input before opening output and uses exclusive creation to avoid overwriting an existing file.
The recipe rejects duplicate JSON keys, nonstandard constants, non-string fields and strings that cannot be encoded as strict UTF-8. Its 2,000,000-byte cap is a policy for this whole-memory example, not a browser size measurement. CSV quoting is handled by Python's CSV writer; the file uses UTF-8 and newline=''.
Verify values, not only their appearance
import csv,json
with open("unicode-input.json",encoding="utf-8") as f:
    source=json.load(f)
with open("new-output.csv",encoding="utf-8",newline="") as f:
    records=list(csv.reader(f,strict=True))
if not records or records[0]!=["id","label"]:
    raise ValueError("unexpected header")
rebuilt=[]
for row in records[1:]:
    if len(row)!=2:raise ValueError("unexpected width")
    rebuilt.append(dict(zip(records[0],row,strict=True)))
if rebuilt!=source:raise ValueError("string sequence changed")
On 2026-10-11, Python 3.12.14 exported both records and recovered the same ordered records and exact label strings. The Unicode database used by that runtime was 15.0.0. The downloadable evidence contains each label's JSON escape representation, complete code-point list and UTF-8 bytes. These measurements concern our fixture and Python recipe, not the browser tool, every spreadsheet or a database's comparison rules.
This preserves parsed values rather than the original JSON source spelling. A Unicode escape and its literal character may parse to the same string; retain the original JSON file if source formatting or original bytes matter.
What changes when you deliberately use NFC?
Python's normalize function accepts NFC, NFD, NFKC and NFKD. NFC uses canonical decomposition followed by composition. In our executed example, NFC left N1 unchanged and changed N2 to the same sequence as N1. The number of distinct label strings therefore went from two to one.
import unicodedata
original_label = record["label"]
label_for_matching = unicodedata.normalize("NFC", original_label)
# Keep original_label; do not overwrite it with label_for_matching.
Use such a derived field only when the matching contract calls for it. Before deduplicating, group original records by the derived value and review groups containing multiple source values. A label match does not establish that two customer records or identifiers refer to the same entity. Keep record IDs and preserve both original labels instead of silently dropping one.
Do not treat every normalization form as interchangeable
NFKC and NFKD additionally perform compatibility decomposition, which can erase distinctions significant to an application. Choose the form required by the downstream specification. Do not apply normalization indiscriminately to opaque identifiers or overwrite the source just to make a lookup succeed. The two-record example here demonstrates NFC behavior only.
If a join still fails, inspect the code points on both sides and the receiver's collation or matching rules. Do not conclude that the converter corrupted an accent merely because a spreadsheet displays two labels alike. Likewise, the supplied example is not proof that all strings which look similar are canonically equivalent.
Untrusted text can still be interpreted as a spreadsheet formula after CSV import; accurate Unicode preservation and CSV quoting are not formula sanitization.
The same contract in three images
For another exact-string contract, see preserve actual line breaks versus literal backslash-n. For general export checks, see verify rows and fields.