Guides / Failed export protection
JSON to CSV: Keep Your Existing Export When Conversion Fails
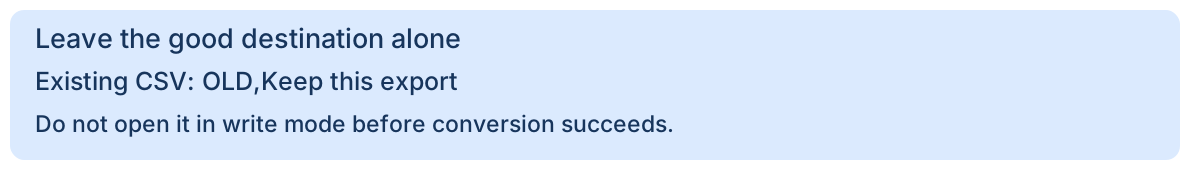
Write a replacement CSV to a new staging file beside the destination, close it, and verify its parsed fields before replacing the existing file. Opening the existing destination with write mode first can discard the good export before conversion succeeds. In our executed failure fixture, direct overwrite loses the old content; staged conversion leaves it unchanged.
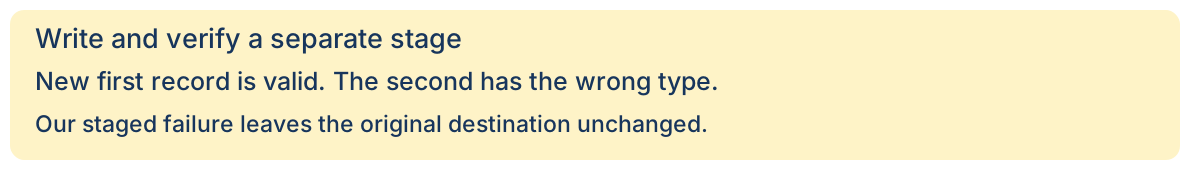
The failure can happen after a valid first record
Suppose a scheduled local export already has a usable CSV from its last successful run. The new JSON document parses successfully, and its first object satisfies the column contract. Its second object contains a number where the receiving schema requires a string. Catching that error does not restore bytes already overwritten.
Existing CSV:
id,text
OLD,Keep this export

New input:
[{"id":"NEW1","text":"valid"},{"id":"NEW2","text":17}]
Our demonstration requires exactly the string fields id and text. The numeric value 17 is valid JSON, but violates that deliberately narrow export schema. This is not a JSON syntax failure or a claim that all CSV converters must reject numbers.
Executed comparison: old destination versus staging
We ran this fictional fixture on 2026-10-22 with Python 3.12.14 on Windows. These are local Python results, not measurements of this site's browser converter.
| Case | Result at destination | What was checked |
|---|---|---|
| Direct overwrite, invalid second record | Header and NEW1 record replace the old contents | Destination bytes differ from known-good CSV |
| Staged write, same invalid input | Original OLD record remains | Exact original bytes unchanged |
| Staged valid replacement | Both NEW1 and NEW2 records are committed | Staged CSV field read-back matches the declared projection |
| Injected exception immediately before replacement | Original OLD record remains | Simulated exception, not a real disk or permission fault |
| Existing target without replacement authorization | Original OLD record remains | Recipe refuses before staging |
The direct-write result contains id,text and NEW1,valid, each followed by CRLF. It is readable CSV, but incomplete as the intended replacement and no longer the old file. Successful parsing alone would not reveal that failed handoff.
Reproduce the staged export in a disposable folder
Download the recipe and fixtures below. Copy the known-good example to a destination named demo-result.csv. Use only demonstration files until you have reviewed the schema and replacement behavior.
python staged-csv-export.py staged-invalid-second-record.json demo-result.csv --replaceThe command fails its string-field check, reports the staging path, and leaves the destination unchanged. Inspect it before trying the valid replacement:
python staged-csv-export.py staged-valid-replacement.json demo-result.csv --replaceThe second command intentionally replaces the destination after checking every staged field. The --replace flag is required for an existing file. Do not supply it unless replacing that particular destination is intended. The script rejects the same source/destination path and a target symbolic link; this does not make it suitable for hostile shared directories or concurrent writers.
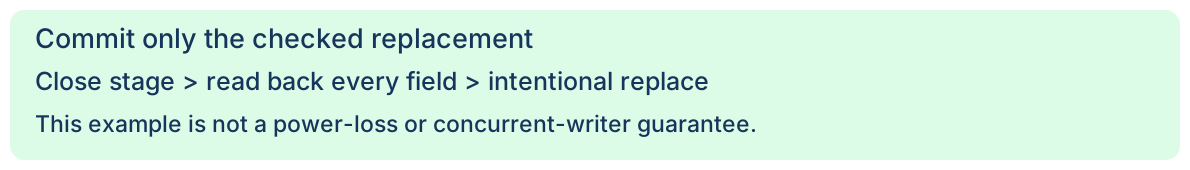
The commit boundary is one explicit operation
write_csv(stage)          # leave destination alone
close_stage_writer()
compare_parsed_fields(stage, expected)
os.replace(stage, destination)  # intentional commit
This outline shows the order; the downloadable file contains the complete runnable implementation. It uses a temporary file in the destination's parent directory, rather than a default temp folder on another drive. Python's os.replace reference describes destination replacement and warns that different filesystems can make it fail. Its atomic-renaming statement cites a POSIX requirement; our Windows fixture establishes only the observed outcomes, not universal filesystem or crash guarantees.
The writer closes before staged read-back and replacement. The temporary-file reference documents platform-specific reopening behavior. An application that still has the destination open can also affect replacement. Report the actual error instead of opening the old destination with write mode as a fallback.
What this recipe promises, and what it does not
The example protects the destination from its demonstrated pre-commit schema error and injected pre-commit exception. It is a single-writer workflow for a trusted local directory. It does not coordinate concurrent producers, preserve every permission or metadata attribute of the old file, or guarantee recovery after power loss. Flush is used to finish Python's buffered writing; this example does not claim an fsync-backed durable transaction.
The input policy is at most 1,000,000 bytes, an array of exact id/text string objects, no duplicate keys or nonstandard constants, and strict UTF-8. This is a code policy, not a measured browser size limit. A failed run may retain an incomplete staging file containing source data. The error gives its path; inspect it and remove it deliberately once no longer needed, rather than confusing it with the successful destination. Do not publish or share staging files automatically.
Question: can an exception handler undo write-mode truncation?
No. A 2020 question about errors while overwriting a Python file describes old content disappearing when the later write fails. Handling an exception reports the failure; it does not recreate the original bytes. Our CSV-specific experiment makes that failure visible after one record, then isolates replacement behind a staged field check. The original question is general file writing, not a report about this converter.
For comparison logic, see Verify Every Row and Field. For a separate source-versus-output receipt workflow, see retain original source spelling separately. Today's problem is protecting the previous destination until a new export passes its checks; those other guides solve different handoff questions.
The handoff in three original diagrams