Guides / Source spelling
JSON to CSV: Preserve Values, Keep Original Escape Spellings Separately
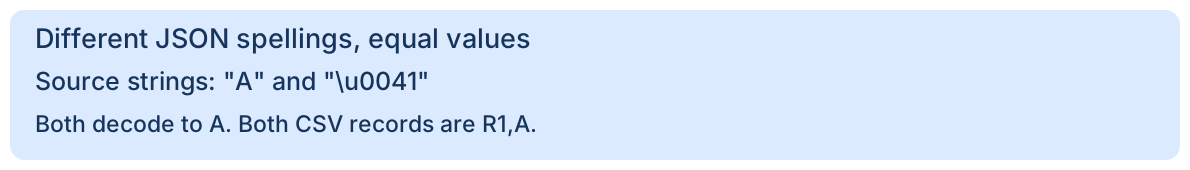
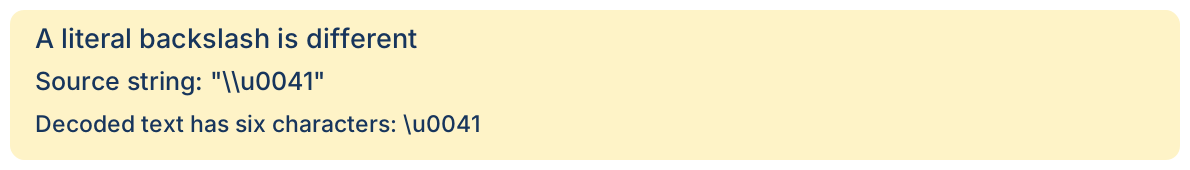
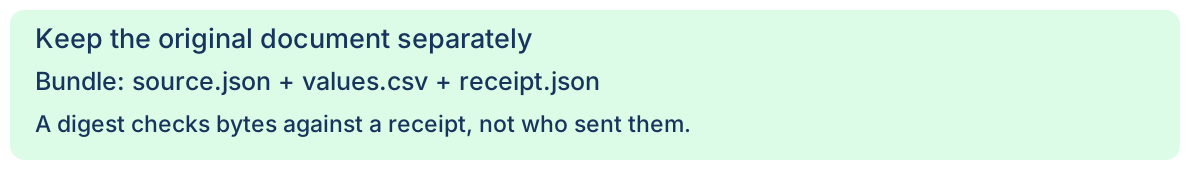
A value-based CSV export cannot tell whether the JSON source wrote "A" or "\u0041": both decode to the same string. Export the decoded value to CSV. If the original spelling matters, retain the original JSON bytes separately and record their digest alongside the CSV. A literal backslash followed by u0041 is a different value; do not decode it a second time.
Three source documents, two CSV results
Imagine comparing a supplier's raw payload with a table sent to a colleague. One producer writes an ordinary letter, another uses a Unicode escape for that same letter. The table is a view of the values, not a transcript of the JSON document. Here are our exact fictional input documents, each containing one record:
plain.json:             [{"id":"R1","text":"A"}]
unicode-escape.json:    [{"id":"R1","text":"\u0041"}]
literal-backslash.json: [{"id":"R1","text":"\\u0041"}]
We executed the downloadable Python recipe on 2026-10-21 with Python 3.12.14, then read its saved files back. These are independent local examples, not tests of this site's browser converter.
| Input case | Decoded text | Saved CSV data record |
|---|---|---|
| plain | letter A | R1,A |
| unicode-escape | letter A | R1,A |
| literal-backslash | backslash, u, 0, 0, 4, 1 | R1,\u0041 |
The first two complete CSV files are byte-for-byte identical: id,text\r\nR1,A\r\n, where the displayed \r\n denotes actual CRLF record endings. All three original JSON files have different SHA-256 digests. The third CSV contains the literal six-character sequence, not the letter A.
Which identity do you need to preserve?
RFC 8259, section 7 defines JSON string escapes. Once equivalent spellings are decoded into the same value, the value alone does not retain which spelling appeared in the source. Decide whether your handoff requires the decoded fields, the original document bytes, or both.
Our bundle keeps both. The CSV answers field-value questions; the saved source answers source-spelling questions. Comparing their checksums with each other would make no sense: they are different file formats serving different purposes.
Reproduce the source-plus-CSV bundle
Use Python 3.12 or later. Download the exporter and an input below, then choose a directory name that does not already exist. The recipe uses an explicit id,text string-only schema.
python source-spelling-export.py source-spelling-unicode-escape.json new-bundleThe new directory contains source.json with the exact bytes read from the input, values.csv with decoded values, and receipt.json containing the schema, record count, runtime version, file lengths and SHA-256 digests. The exporter checks the copied source bytes and reads the CSV back to compare every field before writing the receipt last.
It rejects duplicate keys, wrong or missing fields, non-string values, invalid UTF-8, unpaired surrogate strings and nonstandard constants before creating the bundle directory. Our evidence includes eight rejection inputs and refusal to reuse an existing bundle. It reads at most 1,000,001 bytes and rejects over 1,000,000 bytes: this is a demonstration policy, not a browser capacity claim. A disk error can still leave a partial bundle; absence of a receipt means the run did not finish. Retain it for inspection and use a new destination after resolving the error.
Check a saved source against its receipt
Run this from a folder containing the completed bundle. It hashes the saved bytes, without parsing and reformatting them first:
from pathlib import Path
import hashlib, json
folder = Path("new-bundle")
receipt = json.loads((folder / "receipt.json").read_text(encoding="utf-8"))
for name in ("source.json", "values.csv"):
    data = (folder / name).read_bytes()
    expected = receipt["files"][name]
    assert len(data) == expected["bytes"]
    assert hashlib.sha256(data).hexdigest() == expected["sha256"]
Python's hashlib reference documents the digest operation. Keep the receipt in a separately trusted location if later tampering matters: someone able to change both files and receipt can generate matching replacement digests. An unsigned local receipt establishes neither the sender's identity nor a trusted creation time. Protect the retained source with the same access controls as its data; archiving it does not make sensitive content safe to share.
Will ensure_ascii restore the original spelling?
No. In our executed "A" and "\u0041" cases, json.dumps(parsed, ensure_ascii=True) writes the ASCII letter A in both. The Python JSON encoder reference describes escaping non-ASCII characters with that option; the letter A is already ASCII. An output-encoding policy is not a record of the input's spelling. Reformatting parsed JSON may also change whitespace, so keep the original file when exact bytes are required.
A related question about exporting JSON again
A December 2022 Stack Overflow question asks how to retain Unicode escape syntax after parsing and serializing JSON. That question concerns JSON output, not CSV. For CSV handoffs, separate the requirements: preserve decoded values in the table, choose any required JSON serialization policy explicitly, and retain raw input separately if the exact source spelling must be recoverable. Do not replace characters globally inside an already-generated CSV to imitate the original document.
Keep this separate from newline and normalization problems
This example compares equal decoded values from different source spellings. Actual newlines versus literal backslash-n compares different decoded values. NFC and NFD preservation concerns different code-point sequences that can look alike. Use the relevant field check for each case; a source-byte digest answers a different question.
The recipe uses the standard CSV module with explicit fields and newline handling. Faithful field export does not neutralize spreadsheet formulas or prevent an importing spreadsheet from interpreting text. Use a reviewed text-import workflow for untrusted data. For the broader field check, see Verify Every Row and Field.
Three original diagrams of the handoff