Guides / Semicolon CSV
Export JSON to Semicolon CSV Without Changing Field Text
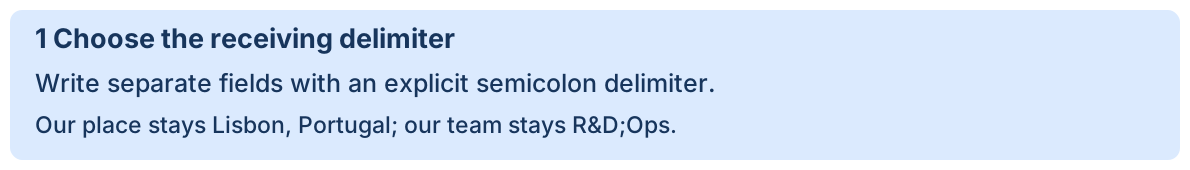
Set the writer and reader delimiter to ;, pass each field as a separate value, and leave punctuation inside strings unchanged. Do not replace every comma in a completed CSV. Our original example keeps Lisbon, Portugal intact and quotes R&D;Ops as one field.
Choose the separator from the receiving contract
Use this recipe when the receiving system explicitly requires semicolon-separated fields. A comma in an address does not by itself require a new separator. The target importer must understand the same delimiter and quoting rules as the exporter. The file extension alone does not select them.
Our fixed schema is id, place, team, with string values only. The third fictional record deliberately includes a quotation mark and a newline so the check has more to prove than the appearance of separators. These are generated examples, not customer records.
[
  {
    "id": "S1",
    "place": "Lisbon, Portugal",
    "team": "R&D;Ops"
  },
  {
    "id": "S2",
    "place": "Paris",
    "team": "QA"
  },
  {
    "id": "S3",
    "place": "Desk \"B\"",
    "team": "Line1\nLine2;QA"
  }
]
What the actual exported text looks like
id;place;team

S1;Lisbon, Portugal;"R&D;Ops"

S2;Paris;QA

S3;"Desk ""B""";"Line1
Line2;QA"
The first place field retains its comma. The first team field is quoted because it contains a semicolon. Quotes inside the third place value are doubled in the serialized file and restored on read-back. The third team value spans physical lines while remaining one CSV field.
Python's CSV format parameters define the delimiter and quoting behavior. With QUOTE_MINIMAL, fields containing special characters are quoted. Open files with newline='' so the CSV layer handles newlines.
python semicolon-export.py semicolon-input.json new-semicolon.csvUse Python 3.12 or later. This separate local recipe does not claim to measure the site's browser converter. The download retains the original JSON; it refuses to overwrite an existing output. A disk-write failure can still leave a partial file, so treat a successful read-back as part of completion.
Why global comma replacement fails this fixture
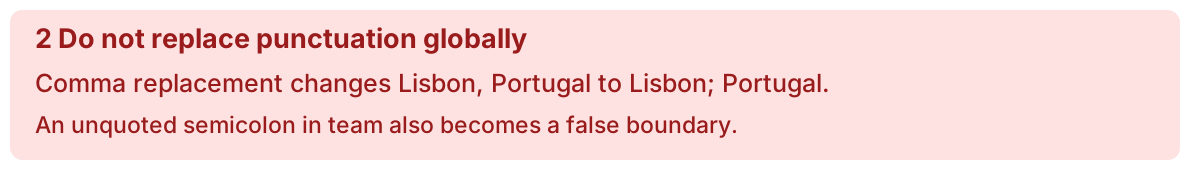
We first exported our same records as comma CSV, then replaced every comma with a semicolon. That changed the content of the quoted place field from Lisbon, Portugal to Lisbon; Portugal. The original unquoted team text also contained a semicolon; after the replacement it was interpreted as another boundary. Replacing separator-looking characters is not equivalent to changing a CSV dialect.
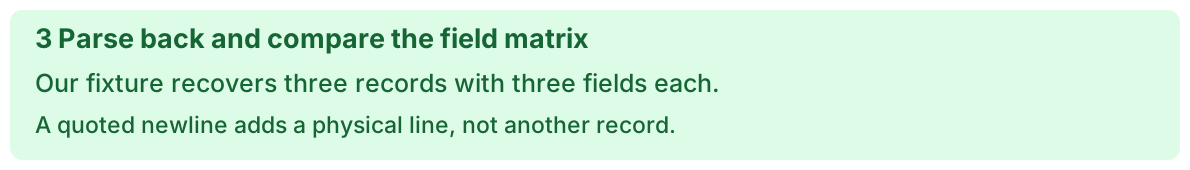
On 2026-10-16, Python 3.12.14 executed both versions. The explicit semicolon version recovered all three records and all three columns exactly. The replacement version did not recover the original field matrix. Download the evidence file to see the complete recovered rows, including where the broken row gained a field.
| Our generated case | Result after semicolon read-back |
|---|---|
| Separate fields, explicit delimiter | 3 records × 3 fields, original strings match |
| Global replacement of comma CSV | Changed field text and mismatched row width |
| Join each row with semicolons before writerow | One field per data record, not three |
Real question: why does a semicolon reader return a whole line?
A 2019 Stack Overflow question, “How to delimit a CSV file with semicolons?” describes this symptom. Our independently generated counterexample passes one already-joined string to the writer. The writer correctly stores that as one field, protecting the semicolons inside it with quotes.
# Wrong shape for a three-column record:
writer.writerow([';'.join(['S1', 'Lisbon, Portugal', 'R&D;Ops'])])
# Pass three separate fields instead:
writer.writerow(['S1', 'Lisbon, Portugal', 'R&D;Ops'])
In our executed joined-row case, every data record read back with width one. Repair the record construction; stripping quotes would destroy the distinction between boundaries and field content. The question is answered here with a new fixture and current Python behavior, not with a copied answer.
Verify the receiving result
Read the exported file using the agreed semicolon dialect. Compare the exact header, every row width and the complete ordered field matrix to the frozen source projection. Our fixture has four CSV records including the header, but five newline characters in its serialized text because a field contains a newline. Counting physical lines is not a record audit.
This demonstration accepts only the declared three string fields, rejects duplicate JSON object keys and nonstandard constants, and limits input to 1,000,000 bytes before parsing. It buffers the output for comparison; the cap is a demonstration policy, not a browser or total-memory benchmark. It does not infer arbitrary columns, convert nested records, or sanitize spreadsheet formulas. Select your receiving application's import delimiter explicitly; no Excel auto-detection result is claimed.
For the wider audit, use Verify Every Row and Field. If repeated values are intentional, preserve each occurrence using the repeated-record guide. This page handles the output separator contract, rather than redefining missing values or normalization.
The same input contract in three images
Return to the JSON to CSV converter for inspectable inputs, or reproduce this explicit-delimiter recipe locally.